Tools we built along the way
Spotlight DQ Know When The Data Stops Deserving Trust.
For teams who should hear about a drifting feed before the people reading the reports do.
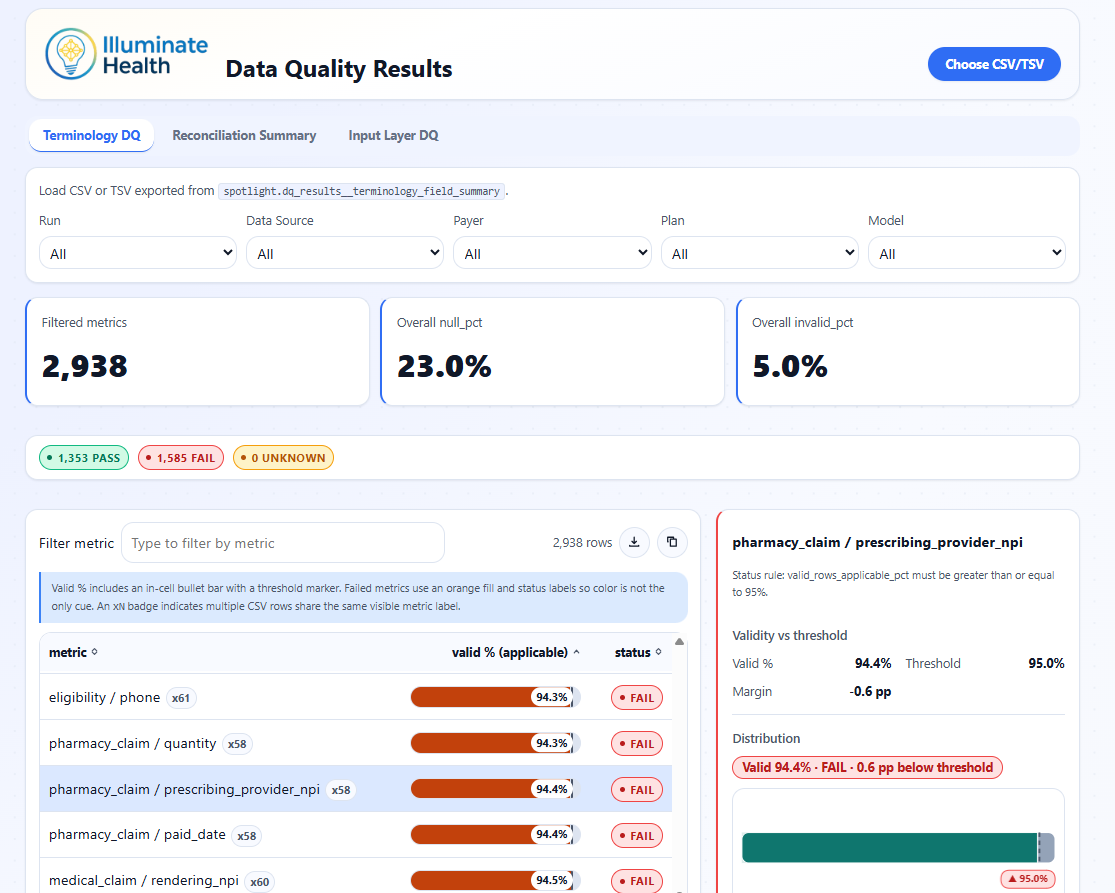
Reconciliation, completeness, and terminology checks that run in your warehouse every release, with aggregate, PHI-safe results and a history that shows whether the data is getting healthier or drifting.
- Runs on
- Any dbt adapter, including Snowflake, Databricks, and Fabric
- Delivered as
- A dbt package plus a results viewer
- PHI
- Aggregate outputs only, no row-level data
- In production
- At a large health system covering about 500,000 lives
Three Checks Every Release, And A Memory Of The Last One.
The checks come ready for a Tuva data model, so there is little to configure and nothing to write from scratch.
-
Reconcile
Claims and enrollment checked against each other every month, by source and plan, so totals make sense.
-
Check completeness
Missing values on the fields that matter, with healthcare rules so fields that do not apply are not flagged.
-
Validate terminology
Codes and identifiers checked against reference terminology: invalid diagnoses, unknown providers, impossible dates.
-
Keep history
Every official run is kept, so comparing this release with the last one is routine.
What Lands In Your Warehouse.
Results are aggregate counts and percentages, so analytics, operations, and leadership can review the same scorecard without anyone getting new access to raw records.
spotlight
dbt package, in your warehouse
- spotlight/ aggregate results only
- reconciliation monthly, by source and plan
- completeness by field
- terminology valid codes, by field
- history every official run
Aggregate outputs only. No row-level PHI.
Any dbt-supported adapter
Buy The Code Once. Updates If You Want Them.
You buy the code, and it runs in your warehouse under your access controls. Keep it as it is, change it, or subscribe to updates as we improve it.
Nothing is priced per member per month, so the cost does not climb as your population or data volume grows. Compute runs on the warehouse you already pay for.
- Built by
- Healthcare analysts who hit these problems on client work, and built the tool to stop solving them by hand.
- Implemented with
- Your team, on your data, with documentation your team can run without us.
- Maintained by
- Your team, since it is your code. An update subscription keeps it current with ours.
Requirements
- Warehouse
- Any dbt adapter: Snowflake, Databricks, BigQuery, Redshift, Spark, or Fabric
- Pipeline
- dbt
- Inputs
- A Tuva data model and its reference terminology
- Configuration
- Minimal; the checks come ready
- Viewer
- Reads exports of the aggregate results
Questions Buyers Ask
How is this different from generic data quality tools?
Generic tools test columns. Spotlight knows healthcare: claim types, which fields apply to which claims, standard terminology, and whether claims reconcile to enrollment. The checks come ready, written by analysts who have chased these problems in production.
Can we share results outside the data team?
Yes. Outputs are aggregate counts and percentages with no patient-level data, so they are safe for scorecards and stakeholder reporting.
What does it cost over time?
You buy the code once. Updates are an optional subscription. Nothing scales with member count or data volume, and the compute runs on your existing warehouse.
Who maintains it after go-live?
Your team can: it is dbt code in your repositories, documented as part of the implementation. If you subscribe to updates, you get our improvements as they ship, and we can support your team directly.
Other tools we built along the way:
Each one follows the same method we use on every engagement.
Plan A Data Quality Review You Will Keep Running.
Thirty minutes with Tom or Brad. Bring the feeds that worry you. We will map which checks to run first and how official runs fit your release cycle.